Echo: Scaling Visual Reinforcement Learning with Off-Policy Experience
Preprint, 2026
Abstract
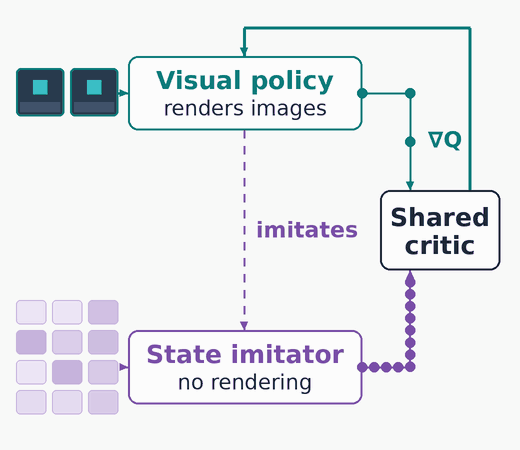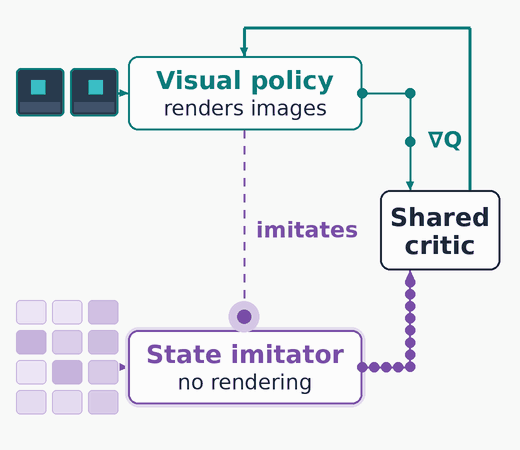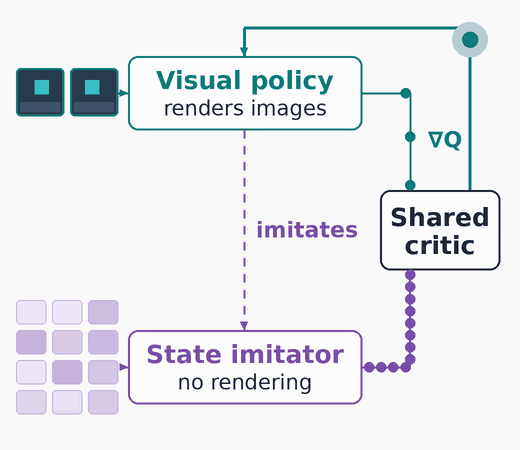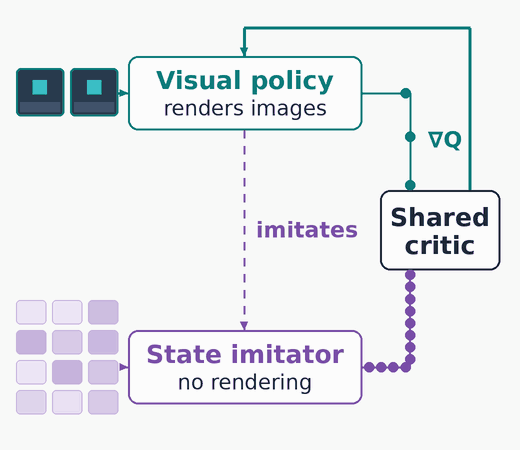
Scaling visual reinforcement learning (RL) with GPU-accelerated simulation is computationally expensive due to rendering and visual-policy inference costs. Consequently, two-stage teacher–student distillation is commonly used to train visual policies, but introduces an imitation gap. In this preliminary study, we introduce Echo, a single-stage off-policy RL framework that scales experience collection without proportionally increasing visual computation. Through inverse distillation, a state-based auxiliary policy imitates the evolving visual policy and collects inexpensive, unrendered experience. Echo leverages this experience for off-policy value learning, directly improving the visual policy through a shared privileged critic. We instantiate Echo with FastTD3 and evaluate it on three visual control tasks and two dexterous manipulation tasks in Genesis. Relative to SDPG under the evaluated configurations, Echo reduces time to reference returns by an average of 60% across the three locomotion tasks and 56% across both hand tasks, while improving peak mean returns by 62% and 12%, respectively. Both hand tasks also achieve higher mean returns at matched simulator-transition budgets. These initial results suggest that scaling off-policy experience is a promising approach to efficient direct visual RL.